Tomorrow Scott and I start our seven-university tour with the ELMCIP Electronic Literature Knowledge Base. We’re visiting a string of excellent digital humanities, digital culture and visualization labs in Chicago and California, and are hoping to learn a lot about what they’re doing and get lots of good ideas for how to further develop the Knowledge Base.
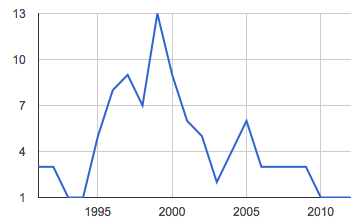
One of the things we’re most interested in is how we can present the increasing amount of data in the Knowledge Base in even more useful ways. The KB includes bibliographic information about creative works and critical writing but also relational links to entries about events at which works are presented, organizations and artist’s collectives that authors have been affiliated with, and syllabi that teach works of electronic literature. We’re interested in developing visualization modules, and in finding ways in which researchers can query the database. Right now we can do simple things by uploading a data dump to Google Fusion or Manyeyes, like this graph showing the frequency of works tagged with “hypertext” in the KB according to their year of publication:
For instance, it would be great to be able to extract answers to questions like these:
- What are the community structures in the field? Do actors form close-knit clusters or are groupings more random and transient? Are these structures stable over time?
- Is there a connection between productivity and particular types of position in the social network of the field (e.g. being part of a closely knit group)? What characterises the community participation of actors whose works are highly referenced?
- What common characteristics do actors who frequently interact and thus belong to a group share? E.g. nationality, residence, age, language, gender, genre they work in?
- Has the speed with which ideas and theoretical paradigms are developed and disseminated internationally increased with the adoption of network technologies? Can literary genres in new media be understood as “memes” which circulate and are developed virally on a transcultural basis?
- Can necessarily reductionist, quantitative, semantically structured approaches to mapping literary and cultural practices enable richer, more expansive analyses of individual artifacts represented within an unfolding historical context?
Here are some of the places and people we’re visiting:
- Art and Technology at the School of the Art Institute in Chicago
- Joe Tabbi, English Dept at University of Illinois at Chicago and director of the Electronic Literature Directory
- Electronic Visualization Lab, University of Illinois at Chicago (Daria Tsoupikova visited us in Bergen last year as a visiting Fulbright Scholar)
- Quinn Dombrowski at the University of Chicago
- Mark Marino, UCLA (who spent a month teaching our students as Fulbright Scholar last spring) (only Scott – I couldn’t bear to leave the kids for more than four nights…)
- Lev Manovich and the Cultural Analytics people at UCSD (Scott only)
- The RoSE project at UCSB, with Alan Liu and Rita Raley (Rita also spent a month with us last spring – we’ve had some great Fulbright visitors!) (I’ll be there for this one!)
- The Stanford Literary Lab (Franco Moretti’s Graphs, Maps, Trees: Abstract Models for a Literary History was very inspirational to us)
Definitely a busy trip, but it should be very inspirational. It’s also our first try at leaving the little ones (aged 2 and 4) for several days with Grandma and Grandpa in Chicago – hopefully this will turn out to be fun for all concerned!
Discover more from Jill Walker Rettberg
Subscribe to get the latest posts sent to your email.
