For just over a year, I’ve been going to Oslo once a month to discuss hindrances for innovation and growth in digital content and services in Norway with an incredibly inspiring group of people: lawyers, consumer rights’ advocates, programmers, a couple of directors of IT-related companies, a security specialist, a musician. Our committee was established by the government, nicknamed Digitutvalget, and led by Torgeir Waterhouse. This Monday, our report “Hindre for digital verdiskaping” was finally released.
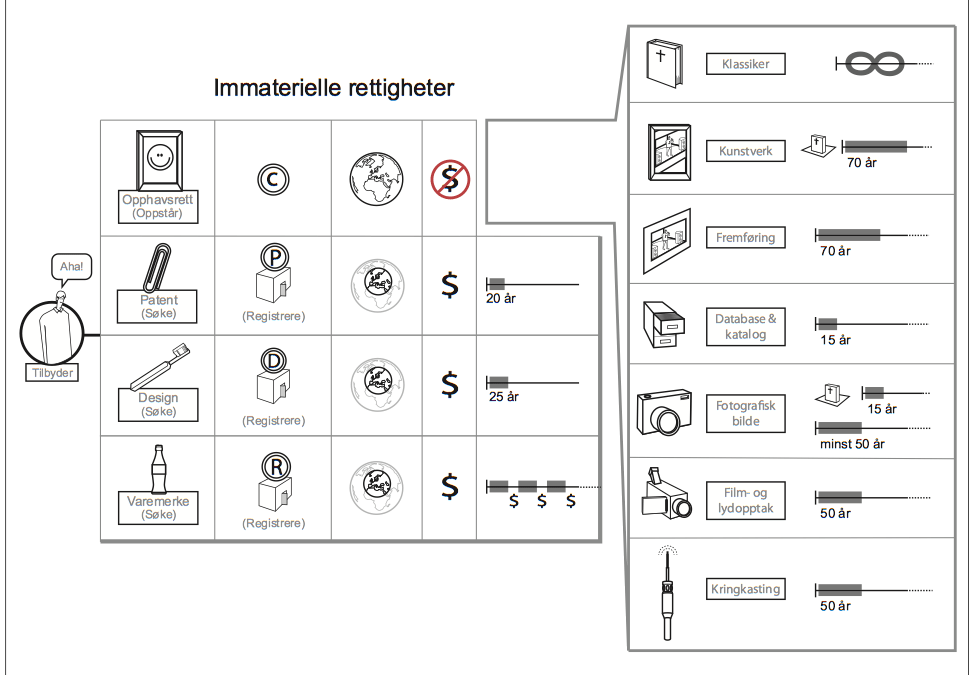
We have some very clear recommendations. For instance, copyright needs to be seriously simplified. We need easier ways to figure out who actually holds copyright and to clear the rights (e.g. through a European copyright clearing house) and we need to reduce the length of time a work is under copyright. Here’s a figure showing how complicated copyright is today:

I want to show you a couple of other juicy diagrams we had made. Here is one showing how money flows in the music industry:

Another fun diagram (I like these) shows how the book industry works. Digital distribution chains are shown in blue.

I’ve learnt a lot from participating in Digitutvalget. I know a lot more about the EU’s copyright and harmonisation rules than I used to, for instance.
And I’m especially keen on our chapter about digital competencies in the general population, and how Norway needs to invest in improving this through education. Among our recommendations in this chapter are the introduction of programming as an option in primary or secondary school (I’d like to see it compulsory from year one, to be honest, but we were trying to be a bit realistic) and introducing requirements that higher education consider learning outcomes for all courses considering whether digital competencies specific to the discipline are adequately covered. Today police officers, nurses, historians, lawyers, bureaucrats, economists, journalists and teachers (and just about any other profession you can think of) all need to understand enough about technology to know when and how to integrate it in their work, and to be able to make decisions about purchasing and implementing IT systems. The 22 July report showed us the police’s miserable use and implementation of IT, and what serious consequences it had, and this is a prime example of how crucial it is that everyone, not just IT-professionals, has some basic understanding of how IT systems work.
There has been some media response to the report. Digi.no hopes that the report will make IT an important discussion point in the upcoming national elections. Several reporters have focused on our recommendation to reduce the copyright period. And Frode Bjerkestrand in BT wrote that Norway is a digital dwarf, and
Discover more from Jill Walker Rettberg
Subscribe to get the latest posts sent to your email.
